DevOps Engineering · 6-month on-the-job experience

Don't learn DevOps tools. Learn how to engineer systems.

Six months building and operating one evolving application. Every tool arrives only when a real engineering problem demands it — so you learn it the way production forces you to.

or 3 monthly payments — ₹20,000 today

See the journey

Live, trainer-proctored · One project, six months · Evidence you can show

The philosophy

Problem first. Tool second.

Conventional courses hand you a ladder of tools. Nexverse hands you a broken, growing, demanding system — and the tools become inevitable.

The conventional way

  • A fixed syllabus marched top to bottom
  • Tools taught in isolation, then forgotten
  • Exercises that end at “it compiled”
  • A certificate as the only evidence

The Nexverse way

  • A business requirement lands — you find the problem inside it
  • You research options, defend a recommendation, get approval
  • You build it, break it, debug it, deploy it, monitor it
  • Every claim backed by repos, pipelines and incident reports

How every problem is worked

  1. Problem
  2. Think
  3. Design
  4. Build
  5. Break
  6. Debug
  7. Automate
  8. Deploy
  9. Scale
  10. Observe
  11. Secure
  12. Improve

…and then the next problem. The loop is the curriculum.

Real problems, not exercises

The tickets you'll actually work

These arrive the way they do at work — vague, urgent and yours. Scroll through a sample of the queue.

“The site is down.”

No alert, no obvious cause. You trace DNS, load balancer, app and database until you can say exactly what failed — and fix it.

NetworkingDebuggingLog analysis

“Deploys scare everyone.”

Manual releases keep breaking Fridays. You design a pipeline where shipping is boring: test, build, release, roll back.

CI/CDTesting gatesRollback strategy

“It works on my machine.”

Dev and production behave differently. You containerize the application until the environment stops being an excuse.

DockerRuntime configParity

“The bill doubled.”

One slow query is hammering the database. You measure, cache, and prove the improvement with numbers.

RedisQuery analysisLatency budgets

“A key leaked to GitHub.”

You rotate credentials, lock permissions down to least privilege, and make the same leak impossible to repeat.

IAMSecrets hygieneLeast privilege

“Traffic spiked and everything crawled.”

One instance can't carry the load. You scale horizontally behind a load balancer and watch the system stay calm.

AutoscalingHealth checksLoad balancing

“Ten jobs are stuck.”

Synchronous processing blocks users. You move work to a queue with retries, dead-letter queues and idempotent workers.

SQSWorkersIdempotency

“Nobody knows what happened last night.”

You wire logs, metrics and traces into one picture so the next incident has witnesses.

PrometheusGrafanaOpenTelemetry

The ecosystem

Every tool here is earned by a problem

Hover or focus a tile to see the job each technology does. None of them appear on day one — each is introduced when your system genuinely needs it.

LinuxThe ground every system stands on
PythonAutomation and glue code
GitEvery change, versioned and reviewable
ReactThe product's frontend, built and shipped
FastAPIThe API layer you operate
PostgreSQLRelational data, tuned and protected
DockerSame runtime everywhere
KubernetesOrchestration when scale demands it
TerraformInfrastructure written as code
AnsibleConfiguration, only where it's genuinely needed
AWSThe cloud your system runs on
S3Object storage with lifecycle and access control
SQSQueues when sync breaks down
LambdaWorkers for background processing
KafkaEvent streaming for many consumers
RedisCaching when latency hurts
GitHub ActionsCI/CD from commit to production
PrometheusMetrics that tell the truth
GrafanaDashboards you'll actually read
OpenTelemetryTraces through every request
NginxRouting, TLS and load at the edge

The six-month journey

One application. Thirteen architectural evolutions.

One application you build and operate for six months: a platform that can eventually manage learners, courses, batches, projects, skills, competencies, assessments, labs, evidence and skill progression. It starts deliberately simple and grows only when a real engineering problem forces it to. Each stage appears when a real engineering problem forces it.

Stage 01 / 13

Application foundation

Triggered by: The business needs a working product to learn, operate and improve.

ReactFastAPIPostgreSQL
Application structureAPIsRelational dataLocal development

This is a reference journey, not a fixed sequence of technologies. The real order follows the problems your platform runs into.

Incident training

Incidents are created deliberately.

Something fails in production on purpose — and it's yours to diagnose, fix and write up. You learn the calm, methodical response that separates engineers from tutorial watchers.

Every drill ends with an incident report: evidence, timeline, root cause, prevention. It becomes part of your portfolio.

incident-drill · production-like environment
  1. 09:41

    Alert: p95 latency above threshold

    Open the dashboard. What changed in the last hour?

  2. 09:52

    Error rate climbing on /api/reports

    Correlate deploy time with the first failing trace.

  3. 10:05

    Database connections saturated

    Find the query. Prove it before you touch it.

  4. 10:20

    Rollback or fix-forward?

    Decide, document the reasoning, execute.

  5. 10:31

    Recovery confirmed

    Write the incident report. Evidence, timeline, prevention.

What you finish with

Evidence, not a certificate PDF.

A real evolving application
GitHub history
Cloud infrastructure
CI/CD pipelines
Testing experience
Deployment experience
Troubleshooting experience
Monitoring experience
Architecture decisions
Technical documentation
Evidence you can show
Portfolio projects
A stronger CV
Real interview stories

At the end you can say, and prove: I built it. I tested it. I deployed it. I monitored it. It failed. I diagnosed it. I fixed it. I documented it.

The engineering ecosystem you'll own

Core engineering

  • · Linux
  • · Python
  • · Git
  • · Networking fundamentals

Application runtime

  • · React
  • · FastAPI
  • · PostgreSQL
  • · Docker

Infrastructure & cloud

  • · AWS
  • · S3
  • · Terraform
  • · Ansible
  • · Nginx

Delivery

  • · GitHub Actions
  • · CI/CD pipelines
  • · Registries
  • · Rollback

Scale & async

  • · Kubernetes
  • · SQS
  • · Kafka
  • · Redis
  • · Lambda

Reliability

  • · Prometheus
  • · Grafana
  • · CloudWatch
  • · OpenTelemetry

Batch information

Your course path and next step.

Loading batches…

Your trainers

Engineers who run production, teaching you to run it.

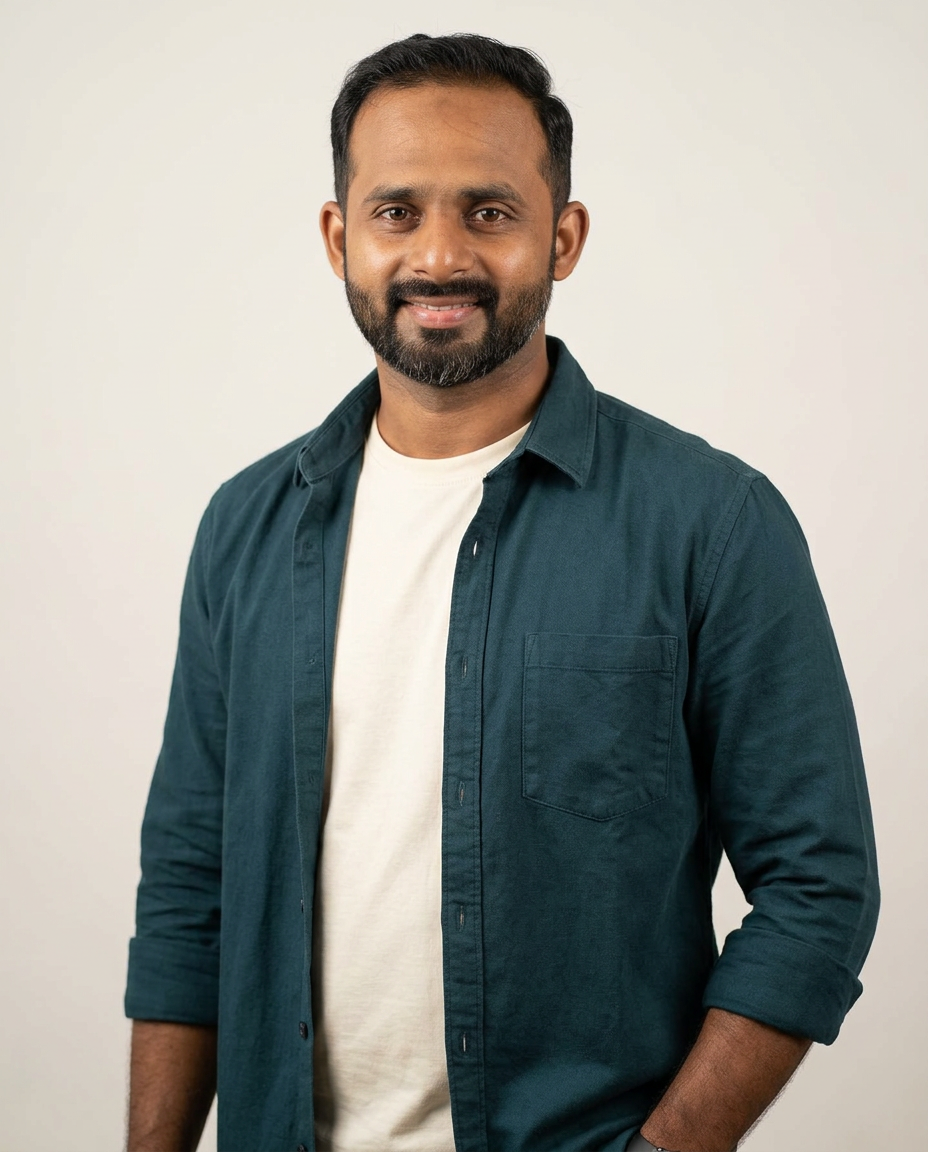
Abuharis Salih, Founder & Managing Director at Nexverse Learning

Abuharis Salih

Founder & Managing Director

10+ years in DevOps. Builds and runs the infrastructure tracks — Linux, CI/CD, containers, Kubernetes and production troubleshooting.

“Everyone should learn by understanding the core technology behind it — otherwise, don't learn it at all.”

Is this for you?

Built for you if

  • You want to be an engineer who owns systems, not a tool collector
  • You can commit real hours weekly for six months
  • You're comfortable with Python basics (or ready to get there)
  • You want evidence — repos, pipelines, incident reports — not a certificate PDF

Not for you if

  • You want pre-recorded videos to skim at 2× speed
  • You want a tool-by-tool syllabus with no decisions to make
  • You can't show up, break things, and explain what you built

Our mission

Learn how to learn. Then learn IT.

Nexverse Learning exists because capable people keep memorising syntax and freezing in front of real systems. This program is the correction: six months of real engineering, with the evidence to prove it.

or 3 monthly payments — ₹20,000 today

Check the Python prerequisite